Pull to refresh
64K+

High performance *

Methods for obtaining systems high performance

107,35
Rating
Show first
Rating limit
Level of difficulty
Format

I Sent the Same PostgreSQL Traffic in Smooth and Bursty Patterns. Average Load Lied

Level of difficultyMedium
Reading time9 min
Reach and readers3.4K

After experimenting with connection pool behavior, I wanted to test another assumption that looks harmless on dashboards.

If two workloads have the same average request rate, are they really equivalent from the database point of view?

At first, it seems reasonable.

If one service receives 1,000 requests per second on average and another also receives 1,000 requests per second, both appear to place roughly the same load on PostgreSQL.

But averages remove timing.

And timing is exactly where queues appear.

So I built a controlled queueing simulation of a Go service talking to PostgreSQL through a connection pool.

This was not a benchmark of PostgreSQL itself. I deliberately kept the model simple because I wanted to isolate one variable: the arrival pattern.

The total amount of traffic stayed the same.

Only the timing changed.

One workload was smooth.

The other arrived in bursts.

The average RPS was identical.

The model behaved very differently.

Read more

I Kept the Same Database Load and Changed Only the Connection Pool Size. Bigger Stopped Helping

Level of difficultyMedium
Reading time9 min
Reach and readers3.8K

After my previous experiment with PostgreSQL latency, I kept thinking about one very simple fix.

If requests spend too much time waiting for a database connection, why not just increase the connection pool?

It sounds reasonable.

More connections should mean less waiting. Less waiting should mean lower request latency. And if the database still has spare capacity, increasing the pool should solve the problem almost for free.

That logic is correct up to a point.

What I wanted to find was where that point actually is.

So I kept the workload unchanged and varied only one parameter: the maximum number of simultaneous database operations allowed by the connection pool.

The result was not that larger pools were bad.

It was something less dramatic and more useful.

A larger pool helped a lot while the system was undersized.

Then, quite suddenly, it stopped helping.

Read more

When PostgreSQL Throughput Looks Fine but p99 Is Already Falling Apart

Level of difficultyHard
Reading time11 min
Reach and readers4.7K

A PostgreSQL service can keep processing almost the same number of requests per second while its slowest requests become several times worse. CPU may still look comfortable, query execution time may barely move, and throughput may remain almost flat. The problem can appear one layer earlier, inside the connection pool, where requests start waiting before PostgreSQL even sees them. This experiment shows how that happens and why p99 usually notices it long before RPS does.

Read more

UUIDv7 and RFC 9562 FAQ

Level of difficultyMedium
Reading time3 min
Reach and readers6.4K

I am a contributor to RFC 9562, and I wrote this FAQ because I kept seeing the same concerns about UUIDv7 surfacing across Hacker News, Reddit, and developer blogs. The discussion would always circle back to the same objections, most of which are superficial and fall apart when you look closer. UUIDv7 is too big. The timestamp leaks creation time. It creates hot shards. It’s slower than BIGINT. Sorting breaks if clocks drift. After encountering these objections repeatedly, I decided to collect the most debated questions in one place and answer them based on real implementation experience.

Get inside info

Async Logging Is Not a Silver Bullet — What Actually Limits Performance

Level of difficultyMedium
Reading time4 min
Reach and readers5.7K

Async logging is often treated as an obvious optimization.

It isn’t.

It just moves the cost somewhere else.

This idea sounds simple: synchronous logging blocks, async logging doesn’t — so it must be faster.

But once you look at what actually happens inside the system, the picture becomes very different.

Libraries like Quill are built around asynchronous pipelines. Others, like spdlog, support both synchronous and asynchronous modes. Some systems — including logme — deliberately mix synchronous formatting with asynchronous output.

Despite these differences, they all run into the same fundamental constraints.

Read more

How to speed up mass data inserts in PostgreSQL when using Spring

Level of difficultyHard
Reading time17 min
Reach and readers10K

A common task in enterprise systems is to load large volumes of data into PostgreSQL — sometimes tens or even hundreds of millions of rows. At first glance, this seems simple: just write a loop in Java and call save() for every record. But in reality, such an approach can be painfully slow. Even a perfectly tuned PostgreSQL instance won’t help if the application is sending data inefficiently.

This article explains how to significantly accelerate bulk inserts when working with PostgreSQL through Spring and Hibernate. We’ll walk through which Spring and Hibernate settings are worth enabling, why they matter, and how much performance they can actually unlock. We’ll also look at how to build your own data-insertion layer for PostgreSQL — one that lets you switch between different insertion strategies, leverage PostgreSQL’s custom capabilities, and parallelize the process. Finally, we’ll see how to integrate this layer with Spring and what real gains each approach can deliver.

Read more

PostgreSQL Gains a Built-in UUIDv7 Generation Function for Primary Keys

Reading time4 min
Reach and readers17K

In late September 2025, PostgreSQL 18 was released. It received the long-awaited built-in function uuidv7(). The uuidv7() function generates UUID version 7 (UUIDv7) identifiers of the binary data type uuid in accordance with the international standard RFC 9562. These identifiers are recommended for use as primary keys. If necessary, the timestamp with the time zone can be extracted from them using the uuid_extract_timestamp() function.

UUIDv7 combines the global uniqueness of primary keys, a negligibly low probability of collisions (unacceptable random matches), and ordering by the generation timestamp. This is achieved without using centralized coordination or MAC addresses. The risk of collisions is no higher than with the previously most popular (random) UUID version 4 type.

Due to ordering by generation timestamp, UUIDv7 results in significantly higher performance and smaller index sizes compared to UUIDv4. The most significant bits of UUIDv7 identifiers can be used as a partition key.

UUIDv7 provides the same performance for CRUD database operations as when using auto-increment (the serial type and its modern equivalent GENERATED ... AS IDENTITY). The time to generate a UUIDv7 identifier is approximately a thousand times less than the record insertion time, so the UUIDv7 generation rate does not affect database performance.

Using UUIDv7 eliminates the fundamental drawbacks of auto-increment:

Read more

How to load test PostgreSQL database and not miss anything

Level of difficultyMedium
Reading time14 min
Reach and readers16K

During load testing of Tantor Postgres databases or other PostgreSQL-based databases using the standard tool pgbench, specialists often encounter non-representative results and the need for repeated tests due to the fact that details of the environment (such as DBMS configuration, server characteristics, PostgreSQL versions) are not recorded. In this article we are going to review author's pg_perfbench, which is designed to address this issue. It ensures that scenarios are repeatable, prevents the loss of important data, and streamlines result comparison by registering all parameters in a single template. It also automatically launches pgbench with TPC-B load generation, collects all metadata on the testing environment, and generates a structured report.

Read more

Samsung expands GPU team: open RTL Designer and Performance Architect positions The team at Samsung that designs the...

Reading time2 min
Reach and readers20K

Samsung expands GPU team: open RTL Designer and Performance Architect positions

The team at Samsung that designs the Xclipse GPU in Galaxy phones with Exynos SoC – is doing expansion. There are multiple jobs available, including positions in the RTL and Architecture teams:

Читать дальше →

На ютюбе вышло видео Сергея Сафонова Как Intel создал ARM, ARM похоронил MIPS, на очереди X86? Видео хорошее, в нем...

Reading time3 min
Reach and readers14K

На ютюбе вышло видео Сергея Сафонова Как Intel создал ARM, ARM похоронил MIPS, на очереди X86? Видео хорошее, в нем нет крупных косяков, но есть крупная дыра (или я просто смотрел невнимательно и пропустил?), отсутствующая информация о ключевом событии. В нем упадок RISC-процессоров в районе 2000 года рассматривается как некая загадочная энигма, а между тем все не просто, а очень просто. Вся индустрия в конце 1990-х ждала выхода процессора Intel Itanium, которому предсказывали взрывной рост и распостранение. Всем остальным процессорам предписывалось в организованном порядке идти на кладбище истории.

Из-за прогнозируемого триумфа Итаниума, HP отказались от своего RISC-процессора HP-PA, который в лучшие годы занимал 40% рынка рабочих станций для автоматизации проектирования электроники. DEC забила на свой RISC-процессор Alpha, на который еще в середине 1990-х спортировали Windows NT. Silicon Graphics перестали использовать MIPS для графики для Голливуда и отделили от себя MIPS Technologies которые стали специализироваться на лицензировании процессорных ядер для встроенных устройств. IBM и даже Sun собирались перейти на Itanium.

Однако когда Itanium вышел, его продажи были в десятки раз ниже чем прогнозировалось. Процессор строился на архитектуре VLIW, как современный российский Эльбрус, и имел те же проблемы. В частности, на такой архитектуре, с несколькими параллельными инструкциями в одном командном слове, трудно добиться хороших бенчмарк на программах общего назначения. Эти параллельные инструкции соединяет в одно слово компилятор, и ему трудно предсказать задержки при работе с памятью, которые при промахе кэша могут быть десятки и даже пару сотен тактов (при многоуровневом кэше, особенно с многоядерностью). Обычный суперскалярный процессор в таком случае просто запускает следующие независимые от доступа к памяти инструкции (см. алгоритм Томасуло), а вот VLIW процессору приходится простаивать.

Читать дальше →

Как разводят венчурных капиталистов на бабки по поводу процессоров Когда в СМИ публикуют статью про новый...

Reading time1 min
Reach and readers23K

Как разводят венчурных капиталистов на бабки по поводу процессоров

Когда в СМИ публикуют статью про новый революционный процессор, но в статье нет бенчмарок, тут все понятно: статью можно игнорировать, это просто мусорный набор символов на экране. А если бенчмарки есть? Тут тоже не все так просто. Лет 10 назад был стартап, который показывал венчурным капиталистам слайды, что их революционно гибкий процессор (который динамически выделял потоки) по тактам в 3 раза быстрее чем старшее ядро ARM. Измерение было с помощью симуляции на уровне регистровых передач и в качестве бенчмарки была то ли Dhrystone, то ли CoreMark/MHz. Но они "забыли" указать на слайдах, что если синтезировать их процессорное ядро c библиотекой ASIC на том же техпроцессе, на котором и ядро ARM, против которого они конкурируют - то статический анализ тайминга покажет, что максимальная тактовая частота, которую они могут использовать - втрое меньше, чем у ARM. То есть втрое лучше по тактам умножаем на втрое хуже по частоте = никакого улучшения. Об этом факте я случайно услышал на парти - человек сказал цифру и я сложил два плюс два, то бишь умножил 3 на 1/3.

Также замечу что развод на бабки VC ничуть не менее аморален, чем развод на бабки пенсионеров по телефону, так как в фонды VC вкладывают в том числе и частные пенсионные фонды.

Читать дальше →

Top 10 Google Sheets Features to Enhance Your Productivity

Level of difficultyEasy
Reading time3 min
Reach and readers2.7K

It's been a while since my last appearance, but I'm excited to be back and to share something truly special with you. In this article, we'll explore my top 10 Google Sheets features that are guaranteed to boost your productivity, speed up your workflow, and make your data handling more efficient. So, without further ado, let's dive into these game-changing tools!

Read more

Verilog Meetups @ Hacker Dojo: the status and the plans for 2024

Reading time9 min
Reach and readers4.9K

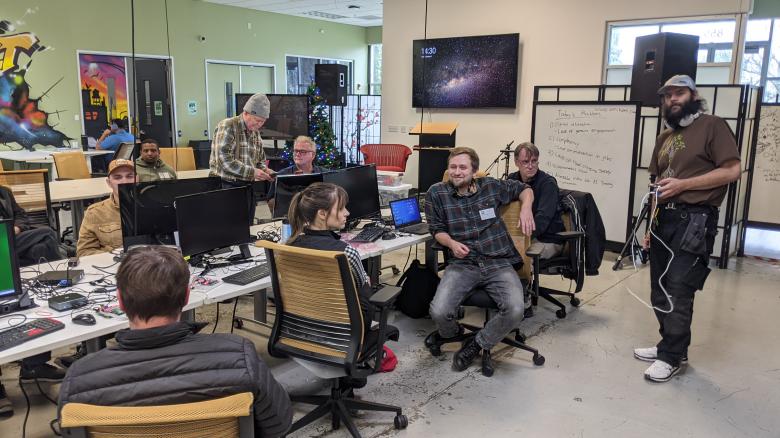
The first meetups of the Portable SystemVerilog Examples group at Hacker Dojo in Mountain View, California were a kind of brainstorming sessions. We discussed the electronic industry, the essence of modern chip design, and the challenges of educating new design engineers. Then we moved to a new mode of action. We started weekly meetings of the core R&D team with the goal to prepare educational materials for the events for a larger audience. The meetings are generally held on Sundays from 11 pm to 2 pm. If you cannot come to Mountain View, you can join online.

We are focusing on interview-level microarchitectural and CPU design examples, providing FPGA vendor-neutral infrastructure and compatibility with open-source ASIC design tools.

Read more

Spring Cloud Gateway: The Single Point of Entry or Failure – a Path to Non-Blocking API Gateway

Level of difficultyHard
Reading time20 min
Reach and readers6.4K

Hello Habr! My name is Nikita Letov. I am a tech lead of backend development in remote banking services for individuals (or retail department) of Rosbank. In this article I will describe what a point of entry to an app is, when it becomes vital, and how API Gateway can help you. We'll review a traditional blocking pattern based on Netflix Zuul 1.x gateway with all its problems of using, then reactive Spring Cloud Gateway and difficulties of moving to it. Finally, we'll compare these two approaches.

Read more

Portable SystemVerilog Examples for ASIC and FPGA: the results of the meetup on 2024-01-21 and the next steps

Reading time4 min
Reach and readers2.6K

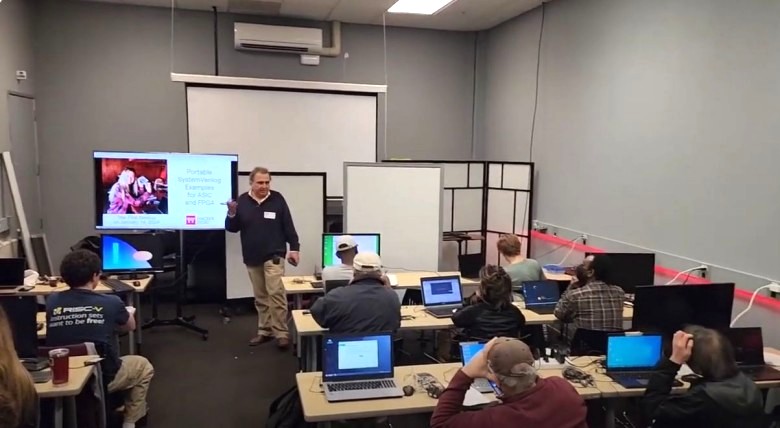
The second meetup of the Portable SystemVerilog Examples group on January 21 2024 at Hacker Dojo in Mountain View, California, went as planned: we moved from the stage of presenting the project to the self-introductions of the participants and the initial tutorial with the first examples. We also started distributing the tasks. The next meetup is tentatively scheduled for January 28 at the same location, from 2 pm to 5 pm. The contents of the meeting will be to work on the examples: basics-graphics-music and systemverilog-homework.

Read more

The next steps after a good meetup on Portable SystemVerilog Examples for ASIC and FPGA

Reading time4 min
Reach and readers1.5K

The meetup on January 14 at Hacker Dojo in Mountain View, California, went well, although not as planned - we spent almost all the time talking instead of doing hands-on exercises. The room we booked can fit 30 people and approximately 30 people did show up. The quality of participants was high: approximately half were familiar with hardware description languages and another half came from various software topics. 12 people filled out the questionnaire despite the fact that I forgot to bring 30 pens.

The discussion during and after the presentation was focused and very meaningful: microarchitecture and education, EDA infrastructure / build scripts, open-source ASIC design tools, the economics of ASIC design and manufacturing, high-level synthesis, transaction-level modeling, ASIC prototyping using FPGA boards, FPGA embedded in ASIC (Menta), new FPGA manufacturers (Gowin) and new design languages - Chisel and SpinalHDL.

Four persons came to me after the meeting to discuss their participation in working on open-source portable SystemVerilog examples, and another seven expressed this intention in the questionnaire. So we are meeting again in Hacker Dojo on Sunday, January 21, at 2 PM, this time not in the classroom area, but in the common shared area.

Generally, I am thinking of having regular meetings, probably on a weekly basis for a small team of developers of the educational materials and on a monthly basis for a wider audience, discussing various design and verification topics.

There were two correspondents of Slavic Sacramento who recorded the video of the presentation. They are going to make it available soon.

Read more

Why would a software engineer attend an FPGA hardware meetup at Hacker Dojo?

Reading time6 min
Reach and readers2.2K

For the last 30 years digital chip design is not a schematic entry anymore: hardware engineers write code just like software engineers.

The difference is that the code software engineer writes becomes a chain of CPU instructions stored in memory, while the code in a hardware description language (HDL) becomes the CPU itself, its transistors and metal connections. And not only a CPU: the same technique is used to design processor-less ("fixed function") blocks in GPU that shuffle triangles and pixels, as well as network router chips that edit packet headers 100 times faster than CPU.

There are ways to experience this workflow without paying a million dollars to a silicon fab. One way is simulation, and another way is to use a matrix of reconfigurable logic cells, a Field Programmable Gate Array (FPGA). You can come on January 14 to Hacker Dojo in Mountain View, California. We have a bunch of computers and FPGA boards, and we will show you how to use them not only to blink LEDs but also to output graphics and recognize music.

This will change your perspective of what the code is.

Prepare for a ride:

How did I increase the website performance score from 35 to 100 for both mobile and desktop?

Level of difficultyEasy
Reading time5 min
Reach and readers2.7K

Not long ago, I started my personal blog. Instead of opting for the traditional route of using the popular WordPress CMS for blogs, I decided to embrace new technologies. My choice landed on Next.js and a NoSQL-type database.

Read more

Synchronous Request-Response using REST and Apache Kafka

Reading time8 min
Reach and readers12K

At first glance making REST and Apache Kafka compatible seems quite a challenge. However Innotech team nailed the task. Kirill Voronkin, Lead Developer at Innotech, shared the details on transforming unsynchronized queries into synchronized.

Read more